dots.tts
Featuring ultra-realistic 48kHz zero-shot voice cloning with rich emotional and lifelike expressiveness
Note: Please open in the PC Client. Go to download >>>
Features
Supported Languages
Dialects
System Requirements
16GB RAM recommended. 18GB+ storage recommended.
macOS 15+: M-series chips required.
Windows 10/11 64-bit: NVIDIA GPU with 8GB+ VRAM required.
Note: For NVIDIA GPUs, install a newer driver.Screenshots
Introduction
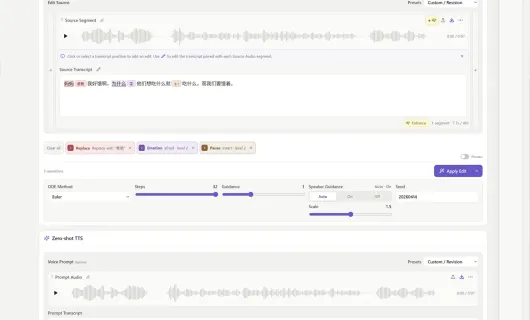
Updated 2026-08-26: Added support for more high-efficiency models and the new Speech Editing feature. Users who installed before this date can click "Reinstall / Update" to get the latest version.
Only the dots.tts-mf model is downloaded by default, which meets the needs of most users.If you select the dots.tts-soar model, the program will automatically download the corresponding model, which will take up an additional approximately 10 GB of disk space.
dots.tts is a cutting-edge, open-source text-to-speech (TTS) system developed by the RedNote (Xiaohongshu) AI Team (HI-Lab). This project represents a state-of-the-art advancement in the open-source community, designed to deliver ultra-high-fidelity, highly expressive, and multilingual voice cloning.
Core Functions & Product Features
For general users and developers, the most intuitive capabilities of this project can be highlighted through the following pros and cons:
- Instant Zero-shot Voice Cloning: With just a 3-second reference audio sample (even without a text transcript), the model can instantly capture the speaker's unique voiceprint and synthesize completely new text in that specific voice.
- Studio-Grade Audio Quality: Unlike traditional TTS systems that usually output 16kHz or 24kHz audio,
dots.ttsnatively outputs ultra-clear 48 kHz high-fidelity audio, preserving rich vocal details. - Exceptional Emotional & Paralinguistic Expressiveness: It can flawlessly replicate human speech nuances, including breathing, sighing, stuttering (e.g., "uh", "w-well"), and dramatic emotional shifts like sadness, anger, and joy, minimizing the typical "robotic" AI feel.
- Robust Multilingual Capabilities: It natively supports 24 languages and can smoothly transition between mixed-language texts (such as code-switching between Chinese and English) without any unnatural pauses.
- Hardware-Friendly (via MF Distillation): The optimized MeanFlow version requires only 4 inference steps to output audio, boosting generation speed by up to 2.5x, making it ideal for local deployment on consumer-grade GPUs or laptops.
Applicable Scenarios
- Content Creation & Audiobooks: Generating voiceovers for social media videos (like RedNote/Xiaohongshu clips), podcasts, or narrating audiobooks with vivid emotional range.
- Smart Assistants & Conversational Bots: Powering AI companions or customer service bots with real-time, low-latency, and human-like voice responses.
- Cross-lingual Broadcasting: Voice cloning across different languages for cross-border e-commerce or international conferences.
Underlying Core Technology
The architecture of dots.tts completely discards the traditional "discrete token (quantization)" approach used by many mainstream TTS systems (like VITS or early autoregressive models).
Instead, it utilizes a fully continuous, end-to-end autoregressive structure. The backbone seamlessly pairs a semantic encoder, a Large Language Model (LLM), and an autoregressive flow-matching acoustic head over a 48 kHz AudioVAE (Audio Variational Autoencoder). Because there are no discrete tokens anywhere in the pipeline, the system achieves lossless audio quality and remarkably smooth intonation.