Skip to content
BackApp Details
GLM-ASR
Supporting 17 languages, with accurate dialect and low-volume recognition
Note: Please open in the PC Client. Go to download >>>
Features
Supported Languages
Dialects
System Requirements
8GB RAM recommended. 12GB+ storage recommended.
macOS 15+: Supports both Intel and M-series chips.
Windows 10/11: Intel/AMD GPUs supported, NVIDIA GPU recommended.
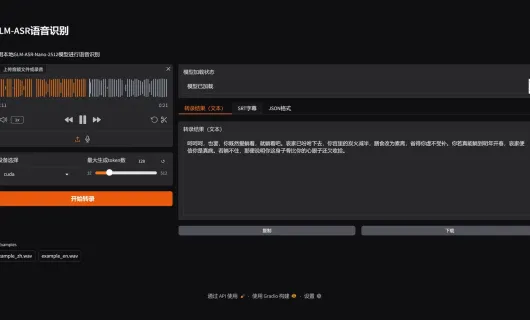
Note: For NVIDIA GPUs, install a newer driver.Screenshots
Introduction
1. Project Overview
GLM-ASR is an open-source speech recognition project developed by the zai-org team. Boasting 1.5B parameters, this model is a lightweight yet high-performance speech recognition solution designed for real-world complexity. It not only accurately processes regular speech but also tackles tough challenges such as low-volume audio, dialects, and noisy environments, while supporting multilingual recognition for wide-ranging applications.
2. Core Features
- Dialect & Low-Volume Audio Support:Beyond standard Mandarin and English, it is highly optimized for dialects like Cantonese. It can accurately capture and transcribe extremely low-volume speech (e.g., whispers in quiet environments) that traditional models often miss.
- Top-Tier Accuracy:It delivers outstanding performance in authoritative Chinese-related benchmarks (such as Wenet Meeting for real-world meeting scenarios with noise/overlapping speech, and Aishell-1 for standard Mandarin). With an average error rate of only 4.10%, it outperforms comparable open-source models and even OpenAI’s Whisper V3.
- 17 Supported Languages:It covers commonly used languages including English, Japanese, French, and German. Among them, 8 languages (e.g., Mandarin, English, Spanish) achieve a word error rate (WER) below 10% (near-native level), and the remaining 9 languages have a WER of no more than 20%, meeting diverse usage needs.
3. Technical Foundation
- Underlying Technology:Trained on the FLEURS benchmark dataset, compatible with the transformers library (to support version 5.x), and adaptable to inference frameworks like vLLM and SGLang for easy deployment and integration.
- Core Advantage:At a lightweight scale of 1.5B parameters, it achieves efficient recognition in complex acoustic environments (e.g., noise, overlapping speech), balancing performance and practicality.
LicenseApache-2.0