Skip to content

BackApp Details
Qwen3-TTS (Lite Version)
Use GGUF quantized model, GPU acceleration for AMD / Intel / NVIDIA, faster startup. Zero-shot voice cloning and natural-language-driven voice design across multiple languages and dialects
Note: Please open in the PC Client. Go to download >>>
Features
Supported Languages
System Requirements
Minimum 16GB RAM. 10GB+ storage recommended.
macOS 15+: Supports Intel and M-series chips.
Windows 10/11: GPU acceleration (NVIDIA / AMD / Intel Arc discrete GPUs) is recommended, with more than 4GB VRAM required. Running on CPU will be slow, and some older CPUs may fail to generate audio.
Note: If you have an NVIDIA GPU with more than 8GB VRAM, you may install the original application.
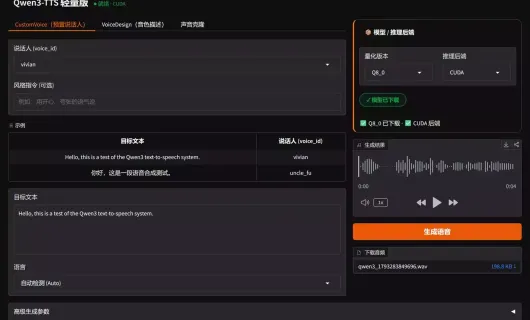
Screenshots
Introduction
Qwen3-TTS is an open-source Text-to-Speech (TTS) model series developed by Alibaba Cloud's Qwen Team. More than just a text-reader, it is an intelligent speech system that understands emotions and masterfully mimics voices. It’s the perfect tool for content creators, developers, and anyone looking to build a unique AI persona.
Highlights:
- Voice Design by Prompting: You can create entirely new voices just by describing them. Simply type "a gentle female voice with a cheerful tone," and it brings that persona to life.
- Instant Voice Cloning: With just a 3-to-5 second audio sample, it can replicate any voice with high fidelity, capturing subtle nuances like breathing and emotional inflection.
- Multilingual & Dialect Mastery: It supports 10 major global languages (including English, Chinese, Japanese, etc.) and is uniquely skilled in various Chinese dialects like Cantonese and Sichuanese, providing a truly local feel.
- Ultra-Low Latency: With a response time as low as 97ms, the speech generation is nearly instantaneous, making it ideal for live streaming and real-time interactive applications.
Technology & Team: Developed by the prestigious Qwen Team at Alibaba, world leaders in LLM and multimodal research.
- Core Architecture: It utilizes a Discrete Multi-Codebook Language Model (LM) architecture. This end-to-end approach eliminates the "robotic" sound of traditional systems.
- Underlying Engine: Powered by the self-developed Qwen3-TTS-Tokenizer-12Hz, the system achieves efficient acoustic compression and high-dimensional semantic modeling, preserving paralinguistic details such as pauses and ambient textures.
LicenseApache-2.0