SoulX-Podcast
Turn Text into Realistic Podcasts with Multi-Speaker, Multilingual & Emotional Speech
Note: Please open in the PC Client. Go to download >>>
Features
Supported Languages
Dialects
System Requirements
Minimum 16GB RAM. 21GB+ storage recommended.
macOS 15+: Supports both Intel and M-series chips.
Windows 10/11: Intel/AMD GPUs supported, NVIDIA GPU recommended.
Note: For NVIDIA GPUs, install a newer driver.Screenshots
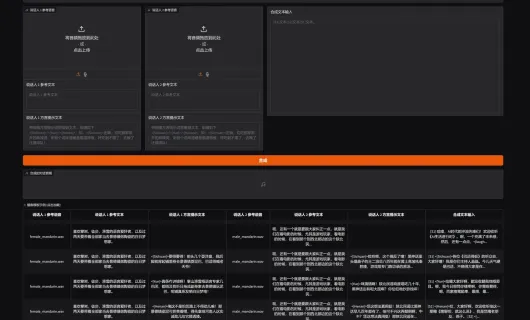
Introduction
If you want to generate speech in a dialect, you can use the following options. If you only want to use the accent of the original language, do not add dialect markers.
Sichuan: Sichuan dialect; Henan: Henan dialect; Yue: Cantonese, Yue dialect.
Paralinguistic Controls (Tone, Emotion)
laughter: Laughing sound; sigh: Sighing sound; coughing: Coughing sound; breathing: Breathing sound; throat_clearing: Throat Clearing sound.
Below are examples of using dialects, where [S1], [S2] represent specific speakers, and <|Sichuan|> indicates the dialect used:
[S1]<|Sichuan|>Oh no, this is reversed!
[S2]<|Henan|>I was just worried you might have trouble on the way!<|sigh|>
1. Project Overview
SoulX-Podcast is an open-source project developed by the Soul AI team, designed to transform text scripts into realistic, high-fidelity podcast-style audio. Think of it as an “AI Podcast Studio”: just input a dialogue script, and it automatically assigns voices to different speakers, adds natural intonations, laughter, sighs, and other expressive elements, generating long-form, multi-turn conversational audio that sounds remarkably human.
It excels not only in single-speaker narration (like audiobooks) but especially in creating multi-speaker, multi-turn dialogues—such as talk shows, interviews, or casual chats—making the output incredibly natural and lifelike.
2. Key Features & Capabilities
- Multi-Speaker Dialogue Generation: Supports dynamic turn-taking between multiple characters, simulating real podcast interactions.
- Multilingual & Dialect Support: Works with Mandarin, English, and several Chinese dialects including Sichuanese, Henanese, and Cantonese, enabling culturally rich content.
- Zero-Shot Voice Cloning: Generate speech in a specific voice using just a few seconds of reference audio—no training required.
- Paralinguistic Controls: Add expressive elements like laughter, sighs, pauses, and emphasis to enhance realism.
- Long-Form Speech Synthesis: Capable of generating extended podcast episodes from long scripts.
3. Technical Foundation & Advantages
- Underlying Technology: Built on advanced deep learning-based Text-to-Speech (TTS) models with end-to-end neural architectures. It integrates cross-lingual and cross-dialectal voice modeling, enabling high-quality, expressive speech synthesis.
- Model Scale: Features a 1.7-billion-parameter model (SoulX-Podcast-1.7B), offering strong expressiveness and generalization.
- Technical Highlights:
- Cross-dialect zero-shot voice cloning: Use a Mandarin reference voice to generate speech in Sichuanese or Cantonese.
- High-fidelity audio output with natural prosody and clarity.
- Fully open-source with Apache 2.0 license, supports local deployment for privacy.
4. Use Cases
- Creating personalized podcast content
- Audiobook and storytelling narration
- Educational audio materials
- Virtual anchors and AI assistant voiceovers
- Preserving and promoting dialect cultures